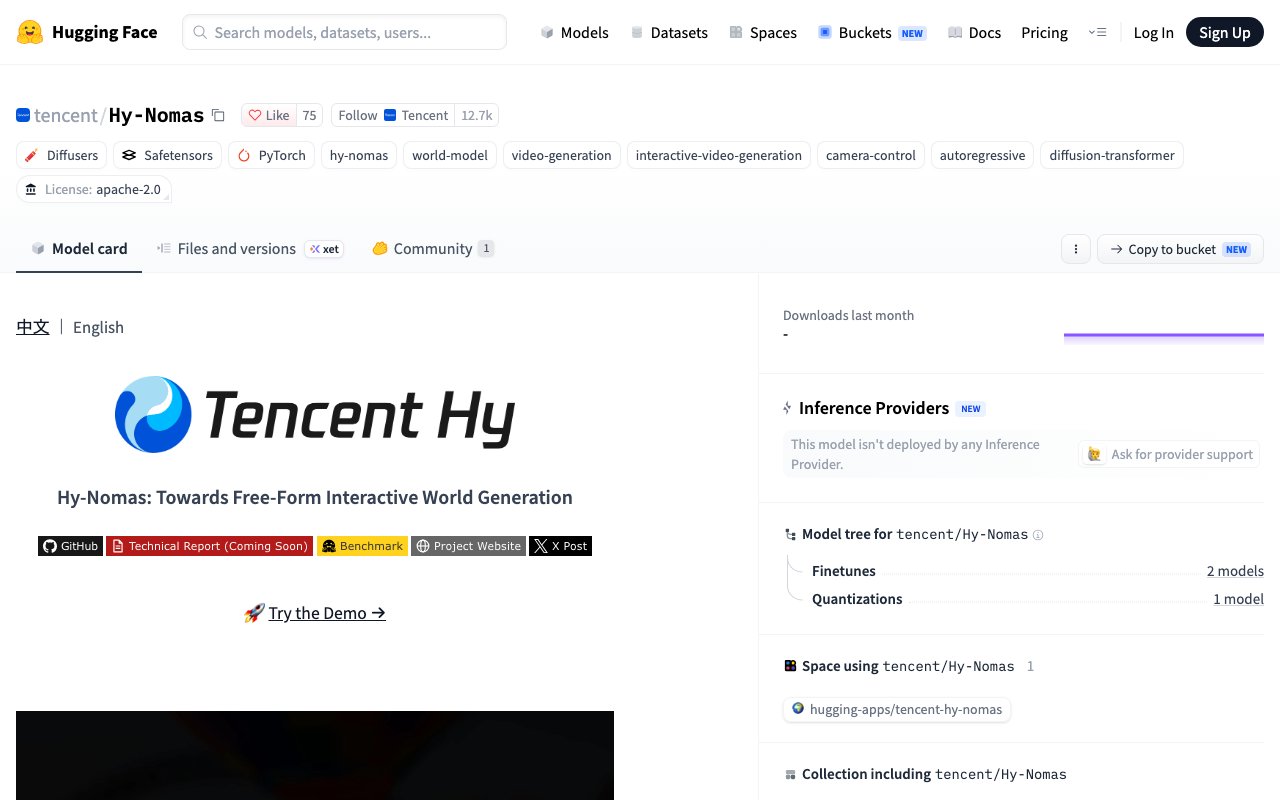
Screenshots show the official pages on the capture date and may differ from the pages at publication. Select an image to enlarge it.
On October 24, 2026 (China time and Japan time), Tencent's Hunyuan team announced on its official X account Hy-Nomas, an AI model that keeps building a video "world." By combining text instructions with camera movements, it generates a scene segment by segment, and along the way users can add objects or change the art style and motion. The model weights and code are available on Hugging Face and GitHub, under the Apache-2.0 license, which is friendly to commercial use.
What Hy-Nomas is
Hy-Nomas is an AI that Tencent calls an "interactive video world generation model." A typical video generation AI produces a video of fixed length from a single prompt. Hy-Nomas instead creates video in short segments and accepts a new instruction each time.
According to the model card, users can do the following during generation:
- Use text to add objects, change the art style or scene, or tell things in the scene how to move
- Specify camera movements to travel through the world
- Alternate between text instructions and camera controls
It has a mechanism that remembers what happened in previous segments (a world memory), which Tencent says keeps the appearance and layout consistent as the scene continues.
Performance and hardware
The released fast version of the model outputs video at 720 pixels tall by 1280 pixels wide and 24 frames per second, using 8 steps of processing. The GitHub description says it supports 4-, 6- and 8-step settings.
The standard setup assumes eight GPUs. However, Tencent also provides a setup that combines INT8 quantization, which makes the model lighter, with offloading some processing to the CPU, so that it can run on a single NVIDIA GeForce RTX 4090 consumer GPU. Note that this single-GPU setup applies to the video generation part only; the prompt enhancement used in the web demo needs separate computing resources.
The 24 frames per second refers to the playback frame rate of the video, and it is not stated whether generation keeps up with real time. The model card also does not list the number of parameters or the maximum video length. The overseas trade outlet VP Land reported "8 billion parameters, up to 60 seconds" as stated on the project page, but CoAI has not been able to confirm this from primary sources.
What was released alongside it
In addition to the model itself, the following were released:
- A LoRA (a small add-on component for extra training) for cinematic visuals
- A LoRA for robotics (trained on data from a real dual-arm robot)
- Code for training, inference and the demo, plus a pipeline for captioning training data
- The Hy-Nomas-Bench evaluation dataset (280 entries)
Tencent explains that the robotics LoRA is meant to improve the ability to reproduce robot motion in the generated world, which suggests the company has robot simulation in mind as well as video production. An online demo that can be tried in the browser is also available.
License and evaluation
The license is Apache-2.0, and it applies not only to the code but also to the model weights. However, bundled third-party components (such as the Qwen model used for reading text) remain under their own original licenses. The LICENSE file states that no further restrictions are added. Some earlier Hunyuan models were released under custom licenses that excluded certain regions or capped the number of users. The more permissive release this time stands out.
On the other hand, no performance figures have been published. Hy-Nomas-Bench tests four areas, namely multiple rounds of text instructions, camera movement, combinations of instructions and camera, and memory of locations, but no scores or comparisons with other models have been released. The technical report is still listed as "coming soon."
The world model race
A world model is an AI that builds a virtual world you can move around in from text or other inputs. Beyond game and video production, world models are drawing attention as a way to train AI for robots and self-driving cars in virtual environments.
Tencent has previously released its HY-World series of world models, and April's HY-World 2.0 was a model that creates editable 3D data. Rather than creating 3D data, Hy-Nomas expands the world by gradually stitching video together, and its distinguishing feature is that text instructions can be inserted again and again. No performance comparison with HY-World has been provided.
CoAI's take
Hy-Nomas is an attempt to take video generation AI from "make it once and you're done" to "keep layering instructions as you create." Because the weights and code are released under Apache-2.0 and there is a setup that runs on a single consumer GPU, it is easy for researchers and developers to try on their own machines.
However, neither performance figures nor the technical report are out yet, so its quality can only be judged from Tencent's demos and explanations. If you want to try it, start by checking how it behaves in the online demo or with lighter settings, and wait for the technical report and outside evaluations before using it in earnest.